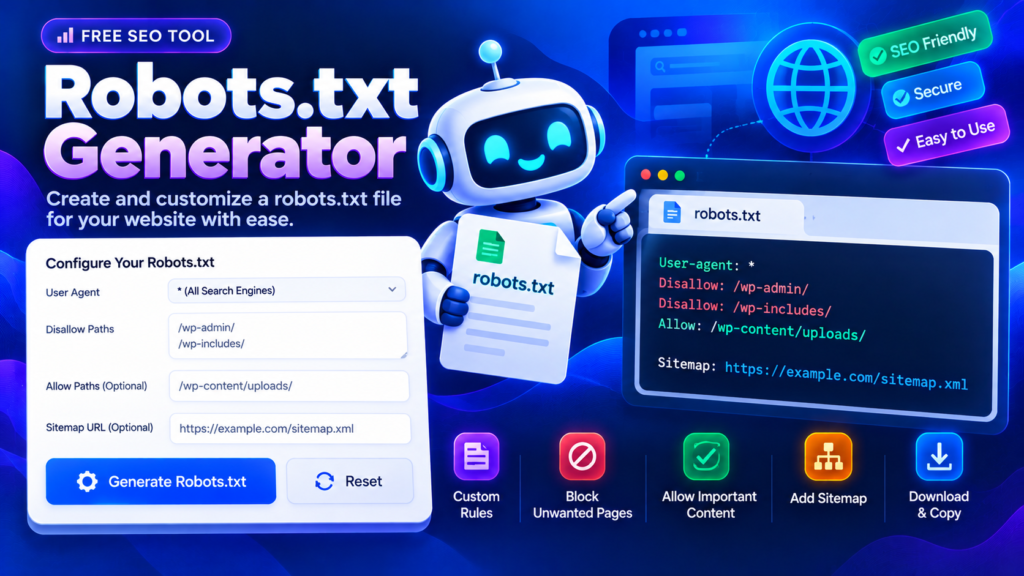
A Robots.txt Generator helps website owners create rules that tell compliant search engine crawlers which parts of a website they may or may not request. A correctly configured robots.txt file can support crawl management, especially on websites with many pages, filters, or administrative URLs. This free tool lets you choose a user-agent, add allow or disallow paths, include a sitemap URL, and download your generated file for review.
Before publishing any crawler rules, it is important to understand what they do. Robots.txt is a set of crawl instructions, not a password or access-control system. Private files and sensitive pages should be protected through proper authentication rather than relying on robots.txt directives.
Robots.txt Generator
Create a robots.txt file by choosing a crawler and adding Allow or Disallow paths. You can also include your sitemap URL, then copy or download the generated text for review.
Choose the crawler to which these rules apply.
Use letters, numbers, hyphens or underscores.
One path per line. Example: /private/
One path per line. Add specific exceptions if needed.
Enter the full, absolute sitemap URL if you have one.
Choose your rules and generate a robots.txt file.
Generated robots.txt
Important: robots.txt gives instructions to compliant crawlers; it is not access control or a security mechanism. Disallowed URLs may still appear in search results without a snippet. Review your rules carefully before publishing them at your website’s root path.
What Does a Robots.txt Generator Do?
A Robots.txt Generator builds a plain-text file using directives such as User-agent, Disallow, Allow, and Sitemap. You can create rules for all crawlers with User-agent: *, or select a specific crawler when you have a clear reason to apply different rules.
For example, a website may wish to reduce crawler requests to an administrative path while allowing a specific public resource. The correct rules depend on your website structure, technology, and indexing goals. Avoid copying a configuration from another site without checking what each path contains.
How to Create Robots.txt for Your Website
Using this robots.txt file generator is straightforward:
- Choose a user-agent from the available options.
- Enter disallowed paths, placing each path on a separate line.
- Add allowed paths when a specific exception is necessary.
- Enter your full sitemap URL if you have one.
- Generate the output and review each directive.
- Copy the text or download the
robots.txtfile.
The generated file is a starting point. Review it carefully before uploading it to your site’s root directory. A mistaken Disallow rule can prevent crawlers from accessing important resources or sections.
Understanding Robots.txt Rules
The main directives are simple but should be used carefully:
- User-agent: Identifies the crawler to which a group of rules applies.
- Disallow: Tells a compliant crawler not to request a matching path.
- Allow: Provides a more specific permission where supported by the crawler.
- Sitemap: Provides the absolute URL of an XML sitemap to help search engines discover it.
Different crawlers may support directives differently. For example, Google documents its supported robots.txt behavior in its official documentation. Check the documentation for the crawler you intend to target instead of assuming every bot interprets every rule identically.
Robots.txt for SEO: Common Mistakes to Avoid
When configuring robots.txt for SEO, do not block an entire website unless that is truly your goal. A directive such as Disallow: / can prevent compliant crawlers from requesting all paths on the site for that user-agent. Likewise, accidentally blocking CSS or JavaScript files may interfere with how a crawler accesses page resources.
Do not use robots.txt to hide sensitive information. A disallowed URL may still be discovered or shown in search results if other pages link to it. Use authentication or appropriate access restrictions when content must remain private.
Also remember that crawl control and search indexing are different things. Robots.txt controls crawling requests; it is not a reliable method for removing a URL from search results. Read Google’s guidance before adding rules to production.
Robots.txt Generator and Sitemap Submission
Adding a sitemap directive can help crawlers discover your sitemap location. Use the full, correct URL, such as the XML sitemap published by your WordPress SEO plugin. A sitemap is a discovery aid, not a guarantee that every listed URL will be crawled or indexed.
You can validate your sitemap with the XML Sitemap Validator. If you are improving URL structure, the SEO URL Slug Generator can help you create readable slugs. To review your search snippet presentation, try the SERP Snippet Preview.
For more background, the Robots Exclusion Protocol overview explains the general purpose of robots.txt files.
Frequently Asked Questions
Where should a robots.txt file be placed?
It is normally published at the root of the relevant host, for example https://example.com/robots.txt. A file in a subdirectory does not generally control crawling for the entire host.
Does robots.txt prevent a page from appearing in Google?
Not reliably. Blocking crawling does not guarantee that a URL will be removed from search results. Use the appropriate indexing controls and access protections for your situation.
Should every website use the same robots.txt rules?
No. Rules should match the site’s structure and technical requirements. Check your CMS, public resources, and crawler documentation before applying them.
Final Thoughts
A Robots.txt Generator makes it easier to prepare crawler directives without manually formatting every line. Use it as a starting point, validate the rules, and verify that important public pages remain accessible to search engines. Careful configuration is more useful than adding a long list of restrictions without a clear reason.
Related SEO Tools
Explore these tools to support your website’s technical and on-page SEO workflow.
- SEO URL Slug Generator — Generate readable, SEO-friendly URL slugs.
- XML Sitemap Validator — Check your XML sitemap structure.
- SERP Snippet Preview — Preview your title and search description.
- Keyword Density Checker — Review keyword frequency in your content.
- Meta Title Length Checker — Review SEO title length.
Trusted External Resources
- Google Search Central: Introduction to robots.txt — Understand how Google processes robots.txt rules.
- The Web Robots Pages — Learn the basics of the Robots Exclusion Protocol.